

Every read is checked.
Every check is recorded.
Each agent acts with its own token, limited to the parts you shared. This page shows how that check works, what is recorded, and the limits we have not solved yet.
Tested on deployed builds, not a demo.
Each agent sees only what its person may see. An agent whose access is revoked, expired or removed is refused on its next call.
No leaks across the 66 tools and routes found that can refuse a request.
Build ec524755 · 17 Oct 2026 · Not yet re-run on the current build.
When two agents write the same fact, one version wins and the other writer is told which one.
Every read path shows the one current version.
Build 2ca31c57 · 20 Oct 2026
Agents see each other's changes within seconds, and a task handed off mid run arrives with its last note and claim.
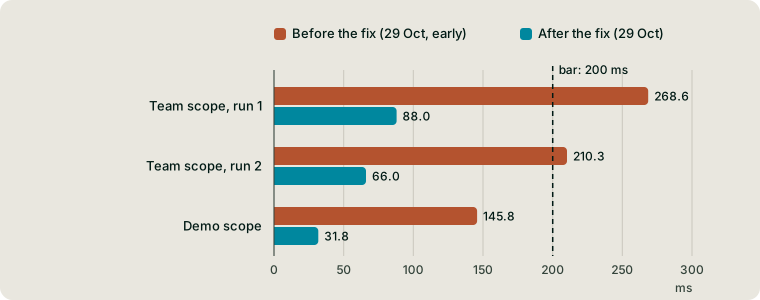
Measured under normal, concurrent and failure load. A later run, on Oct 29, missed the 2-second bar for working notes with six agents posting at once; the chart below shows it.
Build 2ca31c57 · 20 Oct 2026
Disconnect a source and its content stops answering.
Measured on GitHub.
Build 2ca31c57 · 20 Oct 2026
Erase a person and every live store stops returning them, with a record of the erasure.
Erasure that survives a backup restore is not measured yet.
Build 2ca31c57 · 20 Oct 2026
Each answer and refusal from the access check is recorded with who asked, and the app itself cannot edit or delete those records.
A request with a missing or unknown token is turned away before the check, without a record (there is no org to record it against); an expired or revoked token is turned away with a capability.refused record.
Build ec524755 · 17 Oct 2026 · Not yet re-run on the current build.
A source's own sharing list does not come with it. Connecting a source more widely than it was shared needs an explicit confirmation, and that choice is recorded.
A connect without the confirmation is refused and changes nothing.
Build ec524755 · 17 Oct 2026 · Not yet re-run on the current build.
How fast, on the hosted service.
Timed from the client, through the public API and /api/mcp, on one deployment on one day. These are measurements, not guaranteed latencies.
Task-start brief
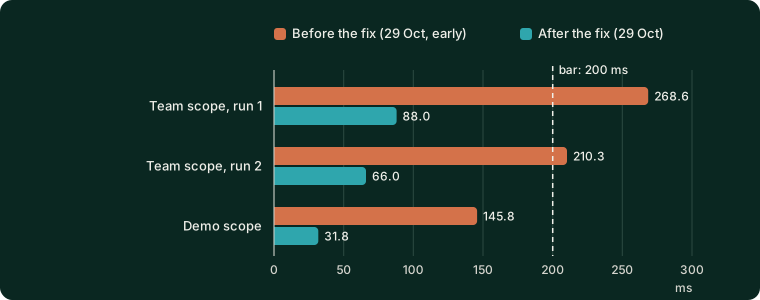
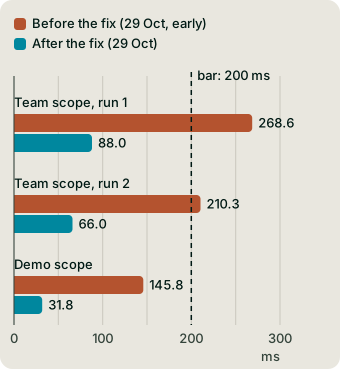
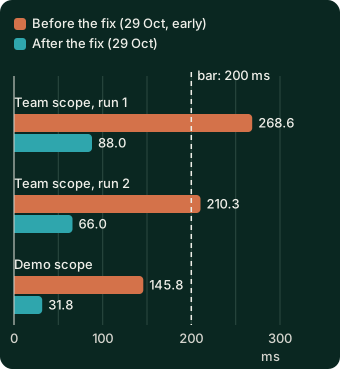
The block of rules, decisions and recent writes on a session's first tool result has a bar: it may add at most 200 ms to that call at p95. Each run opens 40 sessions one at a time and takes the first call minus the second, as the server reports it; p95 is the 38th smallest.
Write-to-read
From just before one agent sends a write until another agent's read returns it, so the network both ways is inside the number. Three loads: one writer at a time, six at once, and every write retried with one writer's token revoked halfway.


Deletion
A fact written by an agent was deleted from a signed-in session, then read by one agent per agent read path until it was gone. All 7 agent read paths stopped presenting it within the 30-second limit; the signed-in web routes were not part of this measure.


Working notes under load: a miss
A working note or claim should reach another agent's next tool result within 2,000 ms at p95, with six agents posting at once for three rounds. The two earlier runs passed; the latest did not.


  Browser / Next.js App Router (RSC + Client Components)
  │
  └── /api/*
        ├── auth gate    Clerk middleware  →  proxy.ts  (every protected route)
        ├── memory/*     check() → GuardedMemoryStore → HybridMemoryStore
        │                     ├── GraphitiMemoryStore   (Neo4j, temporal facts)
        │                     └── PgvectorMemoryStore   (Neon pgvector, MemoryChunk)
        ├── memory/upload   binary file → Vercel Blob → Inngest fileIngest → text → memoryIngest
        ├── sources/*     connect a connector → sourceSync (checksum-gated re-ingest)
        ├── agents/*      Handoff, Architecture and QA workflows
        ├── briefs/*      view · correct (→ dispute / auto-merge) · persist to memory
        ├── facts/disputes  scope-admin resolution, provenance-ranked
        └── access/*      grants and capabilities: mint, revoke, audit

  Inngest background jobs
  ├── memoryIngest   resolveEntities() → distillFacts() → Graphiti + pgvector
  ├── fileIngest     Vercel Blob file → extracted text chunks → memoryIngest
  └── sourceSync     poll a connector → SourceFile checksum diff → memoryIngest

  Hosted MCP  (/api/mcp, Streamable HTTP)
  └── Compatible client → bearer capability → scoped tool execution
        13 tools, each listed under Distribution below
        task-start context and subsequent change notices when available

  Memory service  (Python / FastAPI  :8000)
  ├── /ingest   →  Graphiti.add_episode  (LLM extraction + Neo4j write)
  ├── /search   →  Graphiti.search  (BGE-384 embed → cosine + BM25 → RRF fusion)
  └── /embed    →  BGE-small-en-v1.5  (384-dim, shared with pgvector)

  Access control  (services/access/)
  └── check(ctx, { action, scope })
        ├── human  →  grants JOIN scopes ON path @> target_path  (ltree containment)
        └── agent  →  capabilities WHERE tokenHash = SHA256(token)
                        AND revokedAt IS NULL AND expiresAt > now() AT TIME ZONE 'UTC'
No magic. Just good choices.
Every layer has a reason. Nothing here is incidental.
The hard calls. Every tradeoff documented.
These are the decisions where a reasonable team would choose differently. We chose these for specific reasons and we're living with specific costs.
Hybrid stores in parallel, not one
Decision
General memory retrieval is hybrid: every read queries all the stores the account tier allows (Graphiti, and pgvector's vector and text legs) in parallel, with bounded latency, deduplicates by normalized text and fuses the text leg's ranking by reciprocal rank (k = 60).
Alternative considered
Pick one. Graphiti alone for everything, or pgvector alone.
Cost we're living with
Deduplication layer, two failure modes, two ingest paths per write.
Why
Graphiti extracts clean subject-verb-object facts from short content but degrades on long documents. pgvector retrieves semantically similar chunks but has no concept of entities or relationships. Neither alone handles both cases well. The hybrid combines structured graph facts with semantic document chunks; retrieval can still miss relevant information.
ltree scope tree, not flat RBAC
Decision
Postgres ltree extension: scopes form a tree, a grant on any ancestor covers all descendants.
Alternative considered
Role-based: admin | member | viewer. Three levels, two DB rows.
Cost we're living with
ltree is obscure. Every memory check fires a SQL query with a @> operator. Grant lookup plus an audit-log write adds database work to each check. Complexity lives in the access layer.
Why
Flat roles can't express "EP-1 editor sees EP-1 but not EP-2, and Story Editor sees EP-3 through EP-5." Real enterprise access is hierarchical. ltree containment (@>) handles arbitrary depth in a single index scan.
Scoped tokens for agents
Decision
Short-lived, scoped, hashed tokens. The raw token is shown once. Only SHA-256(token) is stored.
Alternative considered
JWTs issued via OAuth flow, or just pass the user's session to the agent.
Cost we're living with
Custom auth system. No ecosystem SDK. Every agent call validates the token against the DB.
Why
Agents need machine-to-machine auth that works without a user present. JWTs can't be revoked without a blocklist. Session cookies leak the user's full permissions. A scoped capability token expires, is revocable, and is limited to one permission on one scope tree path.
Pre-processing entity resolution, not post-processing
Decision
Normalize entity references before Graphiti sees the text. Aliases, org roles, and CRM names are substituted upstream.
Alternative considered
Let Graphiti extract entities as-is, then merge duplicate nodes after the fact.
Cost we're living with
Every human write goes through the resolver. LLM coreference pass for pronoun references adds latency.
Why
Once Graphiti creates "Tri" as a separate node from "Tri Nguyen", fixing it requires an edge transfer operation that updates every connected relationship. Pre-processing prevents fragmentation for ~0 extra cost. Post-processing graph repair is significantly more expensive and error-prone.
Python microservice for memory, not Node.js
Decision
Separate FastAPI service owns Graphiti, Neo4j and BGE-384 embeddings.
Alternative considered
Node.js-only stack. Use OpenAI embeddings via API instead of local BGE.
Cost we're living with
Polyglot stack. Two services to deploy. Cross-process HTTP on every ingest and query. Shared API key between services.
Why
Graphiti is Python-only. BGE-384 runs in PyTorch, and there's no comparable Node.js solution for local embeddings at this quality. OpenAI text-embedding-3-small is $0.02/1M tokens but adds latency, a vendor dependency, and breaks offline testing.
Single check() chokepoint, not distributed checks
Decision
Guarded memory operations use check() for default-deny authorization and an audit record of the decision. Invalid credentials can be rejected earlier.
Alternative considered
Inline permission checks at each route. Faster, fewer DB queries.
Cost we're living with
Permission lookups and audit writes add database work to memory operations. Scope expansion and individual result checks can add more queries.
Why
Distributed access checks drift. When the same logic lives in 6 routes, one will be missing a case. A shared permission check gives the implementation one policy boundary to test; it is not a guarantee that every external request reaches that check.
Four memory stores, four jobs.
General memory retrieval is hybrid: every read queries all the graph and vector stores the account tier allows, in parallel, and fuses the results; the vector search also matches the words of a query that quotes stored text. Postgres also holds structured conventions and task/session records; Blob retains original uploads for ingestion. These are four storage roles, not an automatic router across four search engines. Keyword and episodic retrieval are proposed capabilities, not additional shipped stores.
Postgres (Neon, relational)
- Identity, orgs, scopes, grants, capabilities
- audit_log: decisions recorded by permission checks
- Conventions, decisions and task/session state
- Identity, access policy and typed application records
pgvector (Neon)
- MemoryChunk: raw semantic chunks for long-form content
- 384-dim BGE-small-en-v1.5 embeddings
- IVFFlat cosine index
- Semantic retrieval when selected by query and tier
Graphiti (Neo4j)
- Temporal facts and relationships; removal is a separate operation
- Entity extraction via LLM
- Group-id partitioned per scope path
- Graph retrieval; may run with vector search
Blob (Vercel)
- Raw uploaded files (PDF, DOCX, images)
- Original files retained as source material
- Supported content is extracted into the ingest pipeline
- Not selected by the general graph/vector search router
Agent access control: scoped tokens, default deny.
Guarded memory operations call the shared permission check. A human has a session and grants; an agent has a capability token. The check records its decision with the actor and scope. A missing or unknown MCP token gets HTTP 401 before any tool runs, unrecorded, since there is no org to record it against; an expired or revoked token gets the same 401 and a capability.refused audit row.
One memory read. An agent's memory_query arrives with its token. check() decides it against grants, the token's scope, expiry and revocation, and writes one audit row either way. A denied read stops there. An allowed read asks every store the tier allows, in parallel and only in the authorized partitions; the results are fused, any replaced version is swapped for its current successor, and the reply names each fact's writer, date and version.
check(): the single chokepoint
// Simplified flow; the service owns the full policy.
check(context, { action, scope, target })

Human:  resolve the actor's grants and scope ancestry.
Agent:  verify the token, actor, permission, scope and lifecycle.
Result: allow or deny; record the permission decision in audit_log.

// Hosted MCP first rejects missing or invalid bearer credentials.
// Those HTTP 401 responses may happen before check() and its audit write.
Actions
memory.read / memory.write / memory.delete / access.manage
Scope tree
org_<id> → dept → account → deal (Postgres ltree)
Token TTL
Default 7 days, max 90 days; an admin token at most 2 hours. Hash = SHA-256. Raw never stored.
Scopes form a tree. The organization acme has two projects, acme.atlas and acme.borealis. acme.atlas has two children, acme.atlas.research and acme.atlas.deploy. A token minted on acme.atlas reads acme.atlas, acme.atlas.research and acme.atlas.deploy. It never reads acme.borealis, a sibling, or acme, its parent.
Revoking a capability stops future requests using that token. Source removal and fact deletion are separate operations; neither revocation nor deletion retracts an answer already returned to another system. Review grants and agent tokens when closing access paths.
Only a person can issue a token, of any permission, so an agent cannot mint or extend its own; a token with admin permission expires within 2 hours. An agent that read content from outside the scope it writes to, such as a sibling or a parent, is refused unless it declares the share; a declared share is recorded and readers of the scope it came from are told.
Every allowed store, in parallel, then fused.
After the check, the graph and the vector store are asked at the same time, each inside the account tier's latency ceiling (4 seconds on team, 10 on enterprise, per store call) and asked once more if it fails. The graph ranks facts by BM25 and embedding similarity, fused by reciprocal rank in the memory service. When a query quotes a line of four or more words, the vector store first runs a trigram text match, then its embedding search. The starter tier allows neither store today, so its read asks none.
One hybrid read. After check() allows it, the graph and the vector store are asked in parallel, each inside the account tier's latency ceiling and asked once more if it fails. The graph ranks facts by BM25 and embedding similarity, fused by reciprocal rank inside the memory service. The vector store first runs a trigram text match when the query quotes a line of four or more words, then its embedding search with the rows the text match found among the candidates, so the text match can bring in a row the embedding search missed. Graph facts and vector chunks are deduplicated by their normalized text, the text match's ranking is fused in by reciprocal rank fusion with k = 60, replaced versions are swapped for their current ones, and a store that still failed is reported as failed.
A replaced version that ranked is swapped for the version that replaced it, and each answer names its writer, date and version. A store that still fails is named as failed in the read's result, never left to look like a store that had nothing to say. Retrieval can still miss relevant information.
A write from a stale read is refused.
Every write of a fact is a version. A write that names the version it read with baseVersion is refused with stale_version: when someone replaced that version in between, and nothing is stored. Clients that never send a base are covered too: the server keeps its own record of every version it served to each agent.
A write based on a stale read is refused, and nothing is stored. Agents A and B both read version v1 of a fact. B writes with baseVersion v1 and its write is stored as v2. A then writes with baseVersion v1; Willder refuses with stale_version naming v2 and stores nothing. A reads v2 with memory_version, then writes with baseVersion v2, which is stored as v3.
Two writes of the same fact within one second, neither writer having seen the other, are a conflict: the version stored first stays current, the other is kept as superseded and stays readable, and its writer is told on its next tool call. Willder detects and reports the conflict; it does not merge the versions.
Sources become scoped, deduplicated memory.
Connectors sync into a scope, files sync into idempotency, and names get normalized before the graph ever sees them.
Connectors
GitHub, Google Drive, Slack, Figma, PostHog. Disconnecting a source stops its content answering; measured on GitHub.
Who can read it
A source takes the access of the scope it lands in. Connecting it more widely than it was shared needs a confirmation, which is recorded.
Idempotency
SourceFile records a checksum per file; a re-sync skips anything unchanged.
memoryIngest: every write, from any source
1. resolveEntities()    EntityAlias registry → org roles → LLM coreference
                         normalizes names/pronouns to one canonical entity BEFORE the graph sees them
2. distillFacts()       LLM extracts 3-10 SVO sentences  (if content > 300 chars)
3. Graphiti.add_episode() → entity extraction → RELATES_TO edges + temporal invalidation
4. pgvector INSERT embedding via /embed endpoint (shared BGE-384 model)An MCP memory server first. The web UI is a client of the same gate.
Connect a client that supports Streamable HTTP and a custom Authorization header. Issue a scoped token from Access → Tokens; Integrations → Connect your AI shows connection guidance. Tool execution uses the shared check() permission boundary. An OAuth-only client cannot use this bearer-token flow directly.
Hosted MCP: no source checkout or database credentials
Endpoint: https://willder.ai/api/mcp
Transport: Streamable HTTP
Authorization: Bearer <your scoped token>

initialize → tools/list → tools/call
memory_query        read
memory_entity       read
memory_version      read
memory_changes      read
memory_note         write
memory_ingest       write
fact_link_source    write
get_my_brief        read
memory_stale        read
contact_search      read
contact_read        read
contact_upsert      write
send_feedback       read

Inspect result.isError as well as HTTP status.
Never place a real token in source control or a prompt.
Three workflows. Shared governed context.
Handoff, Architecture and QA are available from Agents. Choose the workflow, provide its required inputs and inspect the output. Availability does not guarantee that a run succeeds or that a generated answer is correct.
Available workflows
Handoff → scoped handover brief
Architecture      → plan based on selected memory and task context
QA                → checks against a supplied target and available specifications

Each workflow reports its run state and output for review.
External agents can use the same governed memory through hosted MCP.
Follow the quickstart to share one scope, read through that connection and revoke its token. Verify the response and recorded permission decisions. Previously delivered context remains with its recipient.